Four detection tools were run against 40 fully AI-written master’s papers in a peer-reviewed test published 29 June 2026. Three of them caught none. Turnitin scored every one of the 40 below its own reporting threshold. This post collects verified AI content detector accuracy statistics from benchmark studies, vendor disclosures and academic testing published between 2024 and 2026.
AI Content Detector Accuracy Statistics At A Glance
How Accurate Are AI Content Detectors On Benchmark Tests?
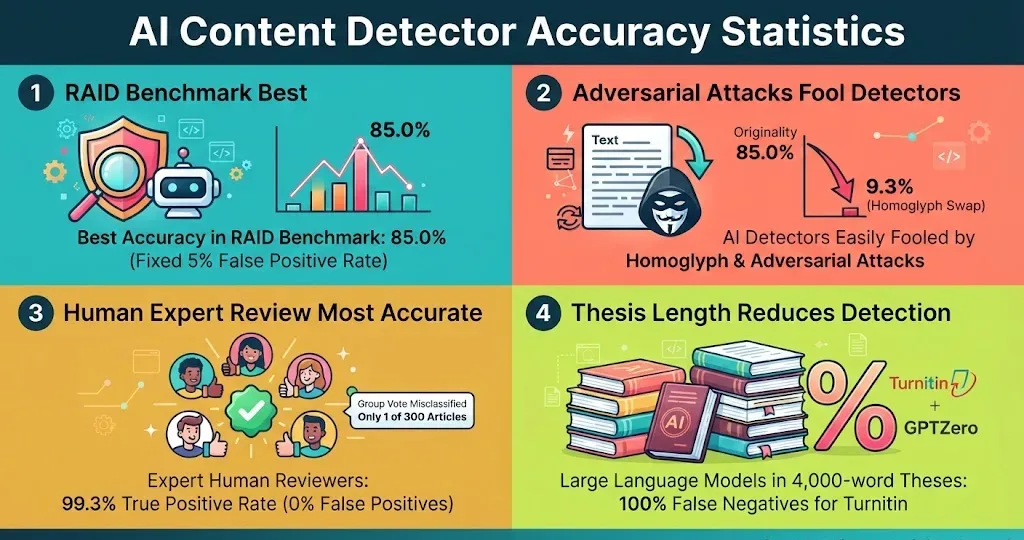
The RAID benchmark tested 12 detectors against 6.2 million generations spanning 11 models, 8 domains, 11 adversarial attacks and 4 decoding strategies. Every detector was tuned to a fixed 5% false positive rate, then scored on the machine-generated half.
Originality led at 85.0%. LLMDet finished last at 35.0%.
| Detector | Type | Accuracy at FPR = 5% |
|---|---|---|
| Originality | Commercial | 85.0% |
| Binoculars | Metric-based | 79.6% |
| Fast-DetectGPT | Metric-based | 73.6% |
| Winston | Commercial | 71.0% |
| RADAR | Neural | 70.9% |
| GPTZero | Commercial | 66.5% |
| ZeroGPT | Commercial | 65.5% |
| GLTR | Metric-based | 62.6% |
| RoBERTa-B (GPT2) | Neural | 59.1% |
| RoBERTa-L (GPT2) | Neural | 56.7% |
| RoBERTa-B (ChatGPT) | Neural | 44.8% |
| LLMDet | Metric-based | 35.0% |
Source: Dugan et al., RAID, Proceedings of ACL 2024, non-adversarial outputs. ZeroGPT was unable to reach the 5% target FPR.
Cross-model generalisation is where the open-source classifiers break. RoBERTa-B, trained on GPT-2 output, scored 84.0% against GPT-2 text and 42.4% against GPT-4 text in the same benchmark.
The RAID authors note that commercial and open-source vendors routinely advertise 99% or higher. No detector reproduced that under fixed-FPR conditions. Students working on Chromebook writing apps for essays and research papers sit inside exactly the document classes these tools were measured on.
AI Content Detector Accuracy Under Adversarial Attacks
RAID applied 11 black-box edits to the same generations. A homoglyph swap replaces Latin characters with visually identical Cyrillic ones. It is invisible on screen and takes one find-and-replace.
Originality fell from 85.0% to 9.3% under it. GPTZero was the outlier, losing 0.3 points.
| Detector | No attack | Homoglyph | Synonym | Whitespace | Paraphrase |
|---|---|---|---|---|---|
| Originality | 85.0% | 9.3% | 96.5% | 84.9% | 96.7% |
| Binoculars | 79.6% | 37.7% | 43.5% | 70.1% | 80.3% |
| RADAR | 70.9% | 59.3% | 67.5% | 66.1% | 67.3% |
| GPTZero | 66.5% | 66.2% | 61.0% | 66.2% | 64.0% |
| GLTR | 62.6% | 24.3% | 31.2% | 45.8% | 47.2% |
| RoBERTa-L (GPT2) | 56.7% | 21.3% | 79.4% | 40.1% | 72.9% |
Source: Dugan et al., RAID, Proceedings of ACL 2024, accuracy at FPR = 5%.
Synonym swaps and paraphrasing pushed some scores up rather than down. RoBERTa and Originality both improved after BERT-based synonym substitution, which the RAID authors attribute to edits that move text closer to the detectors’ own training distribution.
No attacker is needed to break detection either. Adding a repetition penalty during generation cut accuracy by up to 38 points across every detector class, regardless of decoding strategy.
Six commercial tools were tested separately by Perkins and colleagues across 805 tests on 114 samples. Mean accuracy on unmodified AI text was 39.5%, falling to 17.4% after evasion edits. On human-written control samples, only 67% of tests were accurate.
Source: Perkins et al., International Journal of Educational Technology in Higher Education 21:53, 2024.
Can AI Detectors Catch Humanized Text?
Russell, Karpinska and Iyyer had five annotators who use LLMs daily for writing work read 300 non-fiction articles. The group vote misclassified one. Automatic detectors ran on the same 300.
Humanization is what separates them. Binoculars caught 6.67% of humanized o1-Pro articles. RADAR caught none.
| Detection method | Overall TPR | Overall FPR | TPR on humanized o1-Pro |
|---|---|---|---|
| Expert human majority vote | 99.3% | 0% | 100% |
| Pangram (humanizers mode) | 99.3% | 2.7% | 96.7% |
| Pangram (base) | 98.0% | 2.0% | 90.0% |
| GPTZero | 85.3% | 0.7% | 46.7% |
| Fast-DetectGPT | 80.0% | 7.2% | 23.3% |
| Binoculars | 66.7% | 1.3% | 6.67% |
| RADAR | 15.3% | 2.0% | 0% |
Source: Russell, Karpinska and Iyyer, Proceedings of ACL 2025, 300 articles, five expert annotators.
Fast-DetectGPT posts the worst false positive rate in the group at 7.2% alongside a 23.3% catch rate on humanized text. It is the one combination that hurts both parties.
AI Content Detector Accuracy Statistics On Full-Length Theses
Van Vlasselaer, Van Droogenbroeck and Spruyt built 160 master’s-level papers of at least 4,000 words: 40 human-written before 2019, 40 generated with GPT-4o Deep Research, 40 hybrid, 40 humanised. All GenAI text was produced in May 2025.
On the fully AI-generated set, Turnitin recorded 100% false negatives, Copyleaks 75%, GPTZero 70%.
| Tool | Fully AI-generated | Hybrid | Humanised | Fully human |
|---|---|---|---|---|
| Pangram | 65.0% strict / 97.5% inclusive | 92.5% / 95.0% | 92.5% / 95.0% | 100% true negative |
| Turnitin | 0% | 60.0% | 50.0% | 100% true negative |
| Copyleaks | 0% | 30.0% | 22.5% | 100% true negative |
| GPTZero | 0% | 0.0% | 2.5% | 100% true negative |
Source: Van Vlasselaer, Van Droogenbroeck and Spruyt, International Journal for Educational Integrity 22:16, published 29 June 2026, n = 160.
Turnitin’s zero is a reporting artefact, not blindness. It scored all 40 AI papers between 0% and 20%, the band its interface suppresses. The threshold built to protect students from false accusations hid every AI paper in the set.
Two things explain the gap against vendor claims: length and model recency. Copyleaks states on its own site that human text has under a 0.2% chance of being labelled AI-generated, drawn from internal testing on shorter samples. These theses ran past 4,000 words and came from a model newer than the detectors were trained against.
What about false positives?
All four tools classified every fully human paper correctly. The authors report zero false positives for three of the four, with GPTZero showing a small false positive rate in its raw scores, and describe this as a clear improvement on earlier research.
Turnitin AI Detection Accuracy And False Positive Statistics
Turnitin publishes two false positive rates. They measure different things and both are correct.
| Metric | Figure | Period |
|---|---|---|
| Papers reviewed | Over 200 million | Apr 2023 – late Mar 2024 |
| Papers at 20% or more AI writing | Over 22 million (about 11%) | Apr 2023 – late Mar 2024 |
| Papers at 80% or more AI writing | Over 6 million (about 3%) | Apr 2023 – late Mar 2024 |
| Document false positive rate (documents at 20%+ AI) | Under 1% | Stated May 2023 |
| Sentence-level false positive rate | About 4% | Stated May 2023 |
| False positive sentences sitting next to real AI writing | 54% | Turnitin blog |
| Minimum submission length | 300 words | Current guides |
| Scores in the 1%–19% range | Shown as an asterisk, no percentage | Since 8 Jul 2024 |
Source: Turnitin press release, blog posts and product guides, April 2023 – 2025.
Under 1% applies to whole documents scored at 20% or above. The 4% figure is per highlighted sentence inside a report. On a 40-sentence essay, a 4% per-sentence rate means roughly 1.6 wrongly highlighted sentences even when the essay is entirely human.
That 54% of false positive sentences sit beside genuine AI writing is the useful qualifier. Errors cluster at the seam between human and machine passages rather than scattering through clean text.
How Much AI Writing Shows Up In Student Work?
Pangram was applied to 1,163 master’s theses submitted in academic year 2024–2025 at one Belgian faculty. It flagged 529, or 45.5%.
Among flagged theses, mean estimated AI usage was 34.0% and the median 30.0%, with a range of 7% to 100%. The middle 50% ran from 17.0% to 49.0%. No ground truth existed for this corpus, so the authors treat the figures as a distribution of flagging scores rather than confirmed prevalence.
Source: Van Vlasselaer, Van Droogenbroeck and Spruyt, International Journal for Educational Integrity 22:16, 2026, n = 1,163.
Device deployment sets the scale of the problem. Chromebooks hold 60.1% of the global education device market in 2025 (Chromebooks in schools statistics), and reported usage of AI writing and summarisation tools on ChromeOS grew 67% year over year through Q1 2026 (ChromeOS AI tool adoption data). Broader AI usage patterns by age group show students among the heaviest users of these tools.
AI Detector Market Size Statistics
Grand View Research valued the global AI detector market at $581.3 million in 2025 and projects $5,226.4 million by 2033.
| Year | Global AI detector market revenue |
|---|---|
| 2025 (actual) | $581.3 million |
| 2026 (projected) | $749.8 million |
| 2033 (projected) | $5,226.4 million |
Source: Grand View Research, AI Detector Market Report, 2026–2033 edition, base year 2025. Projected CAGR of 32.0% from 2026 to 2033 is the firm’s own forecast.
Academic integrity was the largest application segment at 24.9% of 2025 revenue. Education led the separate end-use breakdown at 31.3%. North America held 33.2% of revenue in 2025. The buyers most exposed to the false positive rates above are the ones funding the category, a pattern visible across education sector technology spending and the wider conversational AI market data.
FAQs
How accurate are AI content detectors?
The best detector in the RAID benchmark reached 85.0% accuracy at a fixed 5% false positive rate. Six commercial tools averaged 39.5% on unmodified AI text in a separate 2024 study, falling to 17.4% after evasion edits.
Can AI detectors be fooled?
Yes. A homoglyph character swap cut Originality from 85.0% to 9.3% in the RAID benchmark. Binoculars caught just 6.67% of humanized o1-Pro articles in the 2025 ACL study.
Does Reddit content get flagged as AI-generated?
Reddit posts were one of eight domains in the RAID benchmark, with 1,979 human-written posts sampled. The authors chose it because first-person informal writing is hard to classify. RAID does not publish a Reddit-only false positive rate.
Why do detectors struggle with newer models?
Training data determines performance. RoBERTa-B, trained on GPT-2 output, scored 84.0% against GPT-2 text and 42.4% against GPT-4 text. GPT-2 itself was trained on pages linked from Reddit posts with three or more upvotes.
What is Turnitin’s false positive rate?
Under 1% at document level for documents scored at 20% or more AI writing, and about 4% at sentence level. Turnitin reports that 54% of false positive sentences sit directly next to genuine AI writing.
Sources
https://aclanthology.org/2024.acl-long.674/
https://aclanthology.org/2025.acl-long.267/
https://link.springer.com/article/10.1007/s40979-026-00226-w
https://www.turnitin.com/blog/understanding-the-false-positive-rate-for-sentences-of-our-ai-writing-detection-capability